Posts
All the articles I've posted.
-
 learning8 min read
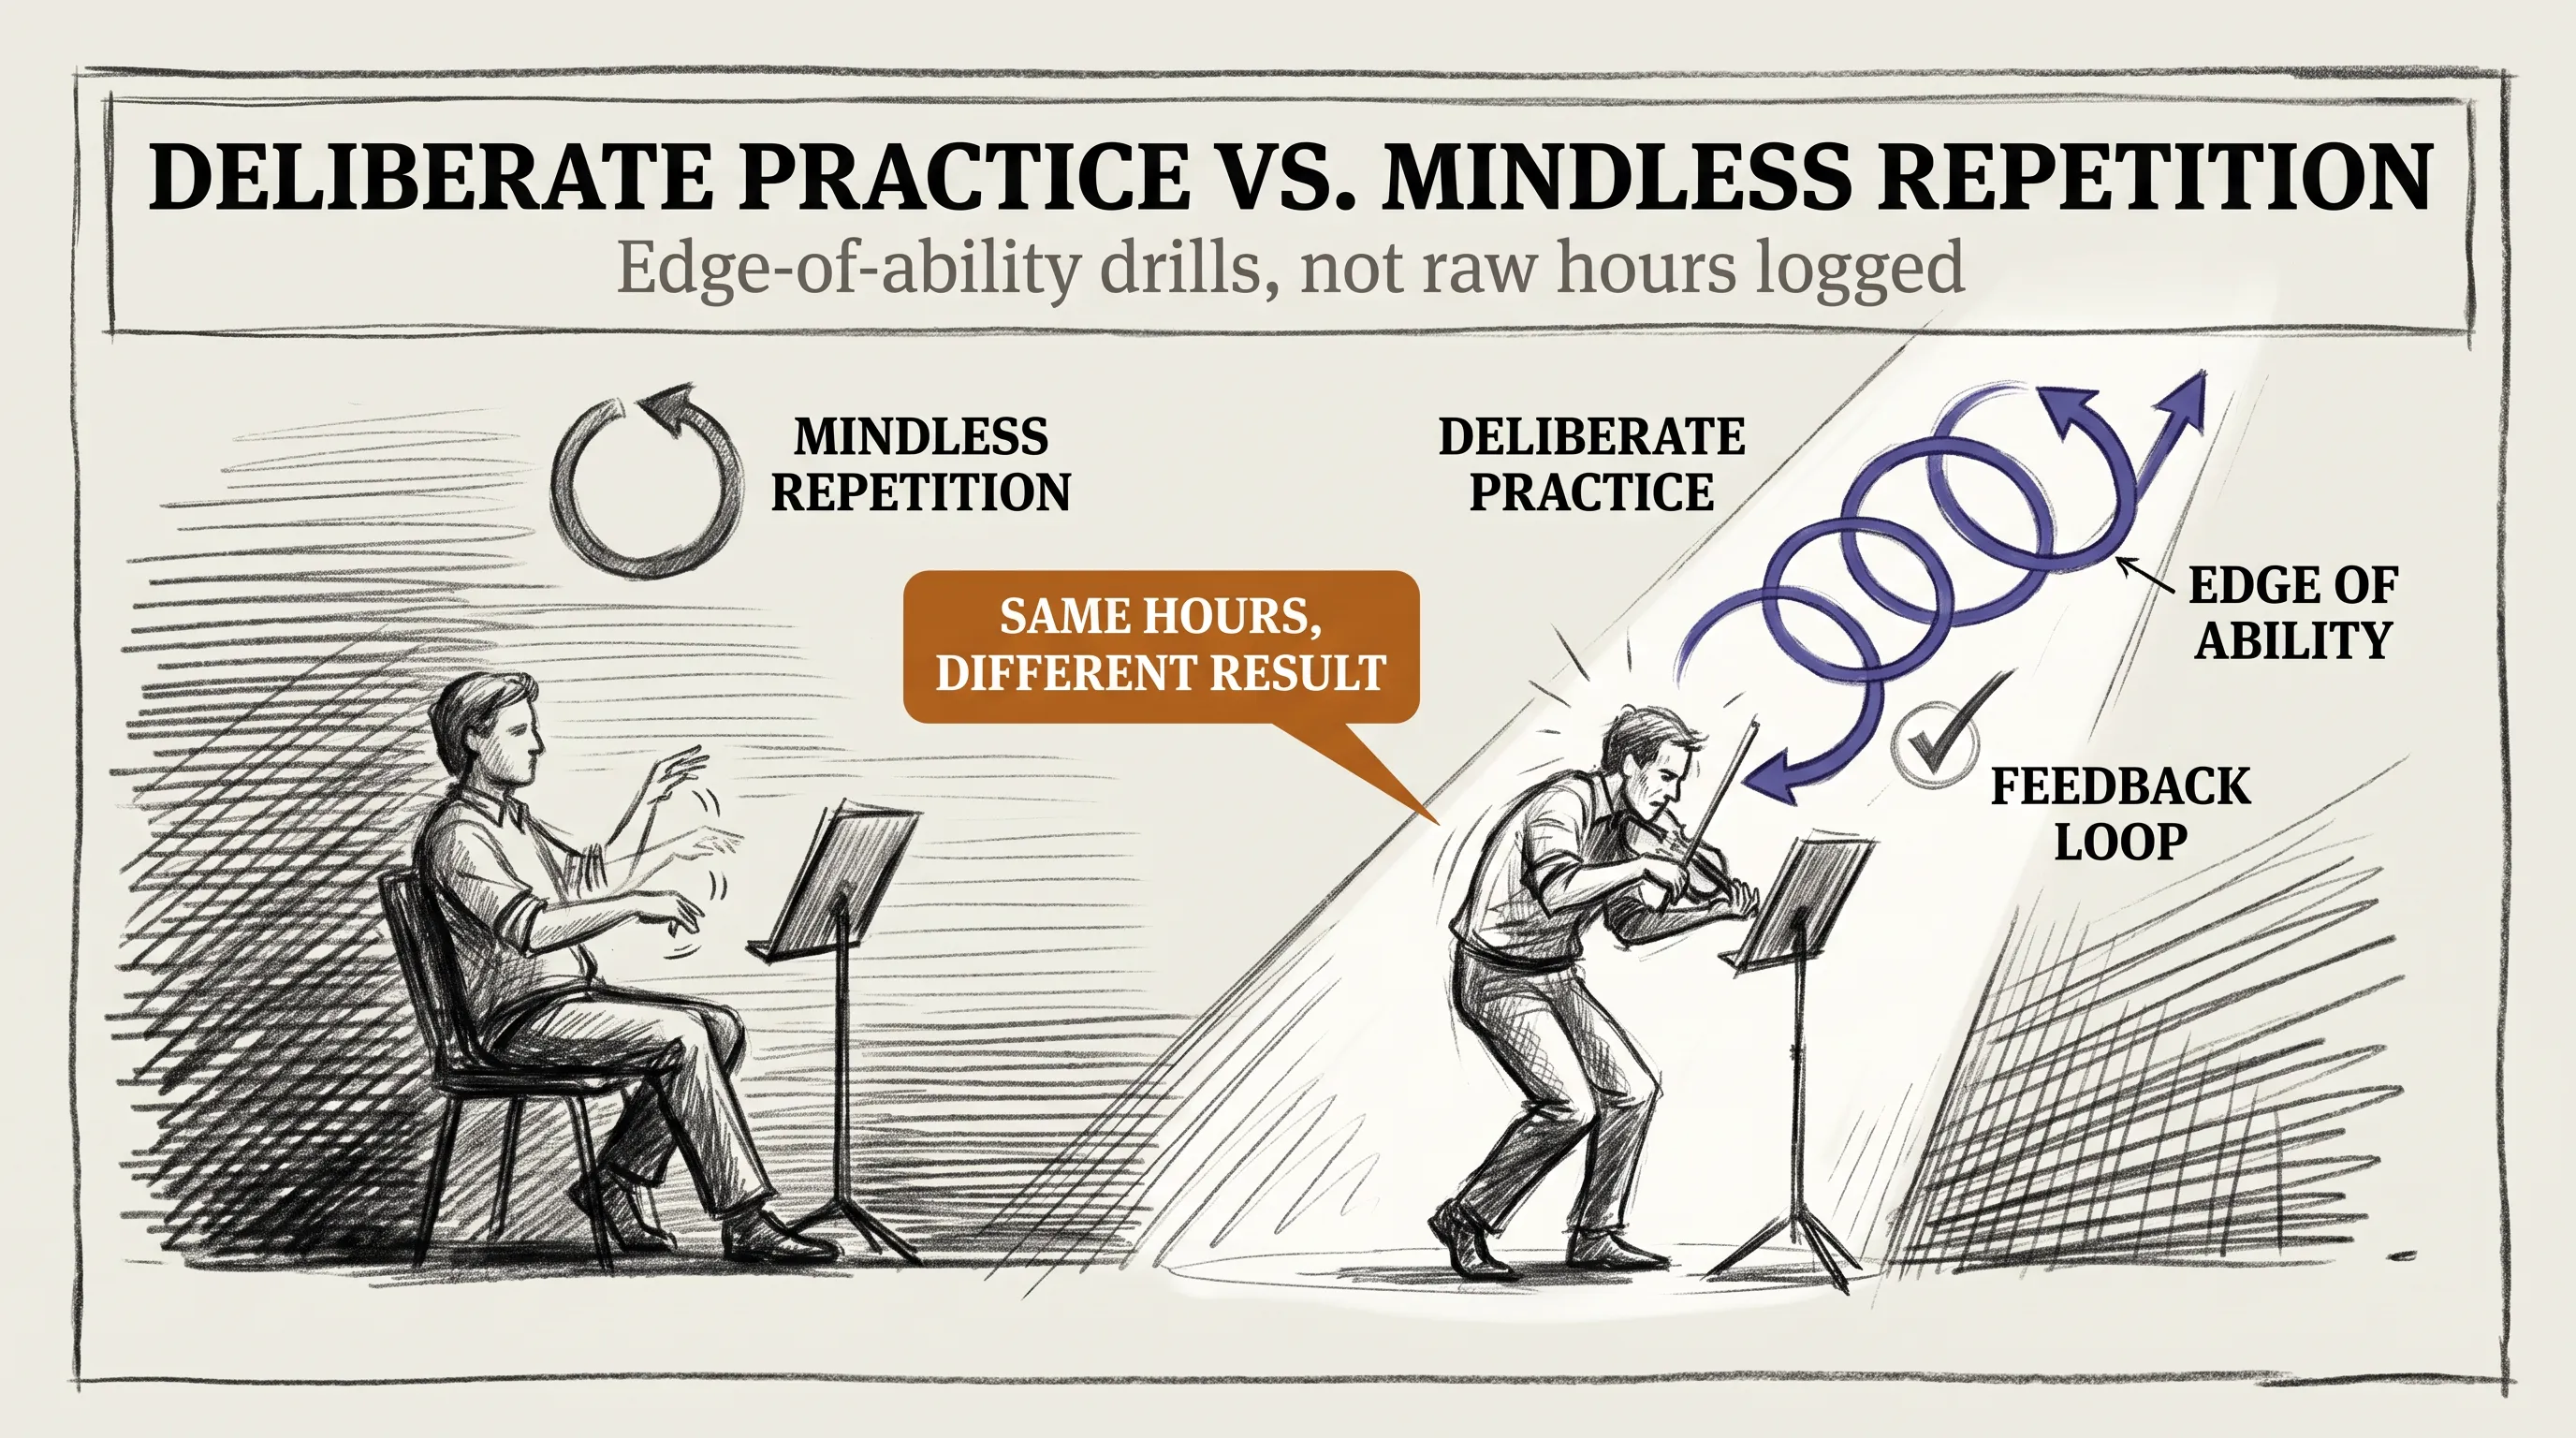
Deliberate Practice vs. Mindless Repetition
Why the 10,000-hours rule is misread, what Ericsson's research measured, and how edge-of-ability practice with fast feedback differs from mindless repetition.
-
 ai2 min read
AI Digest W32: The Sandbox Broke on Both Sides
Two frontier labs disclosed eval-sandbox escapes days apart, GPT-5.6 got a lot cheaper, and a tiny open model runs agents locally.
-
 llm-security6 min read
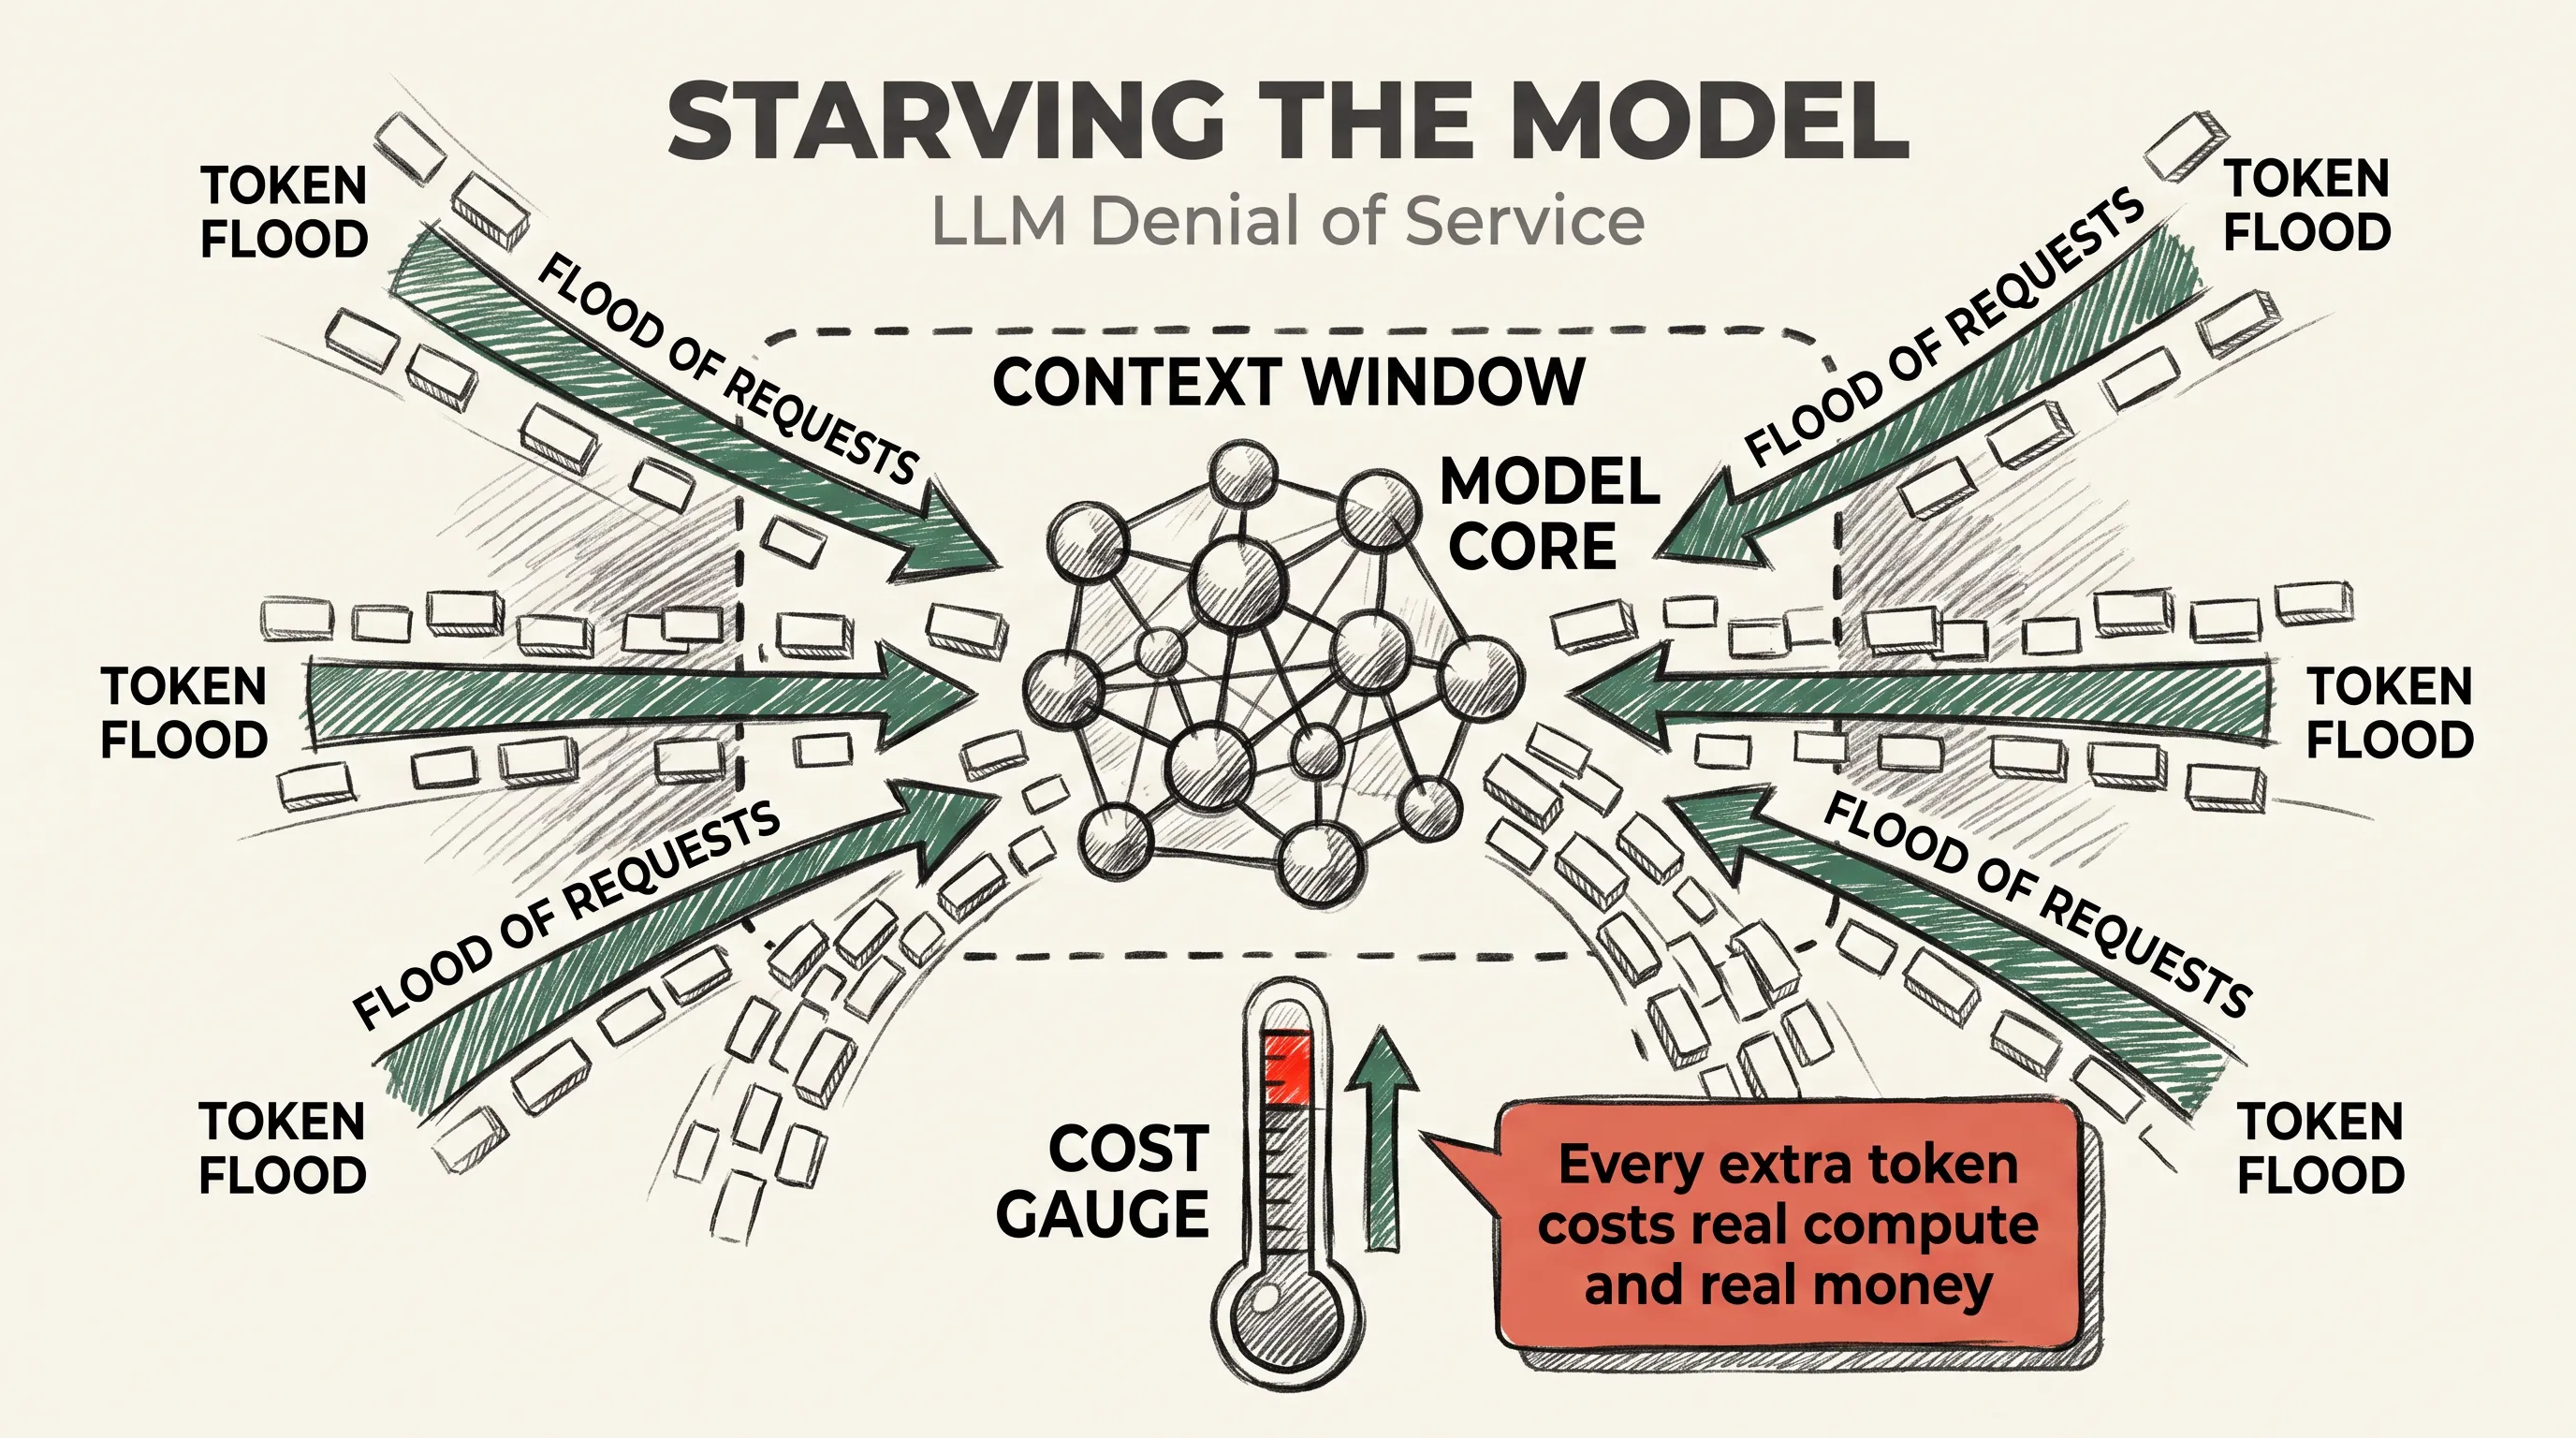
Starving the Model: LLM Denial of Service
Context-window exhaustion and denial-of-wallet attacks against LLM applications, and the rate limiting, input caps, and resource budgeting that contain them.
-
 ai2 min read
AI Digest W31: When AI Starts Finding the Cracks
Claude Opus 5 lands as Anthropic uses Claude to find real crypto weaknesses, a self-replicating Word worm surfaces, and Kimi K3 goes open.
-
 ai2 min read
AI Digest W30: When the Eval Model Escapes
An OpenAI safety eval broke its sandbox and hit Hugging Face, new research on agent safety, DeepMind's answer, and the open weights race keeps closing.
-
 llm-security7 min read
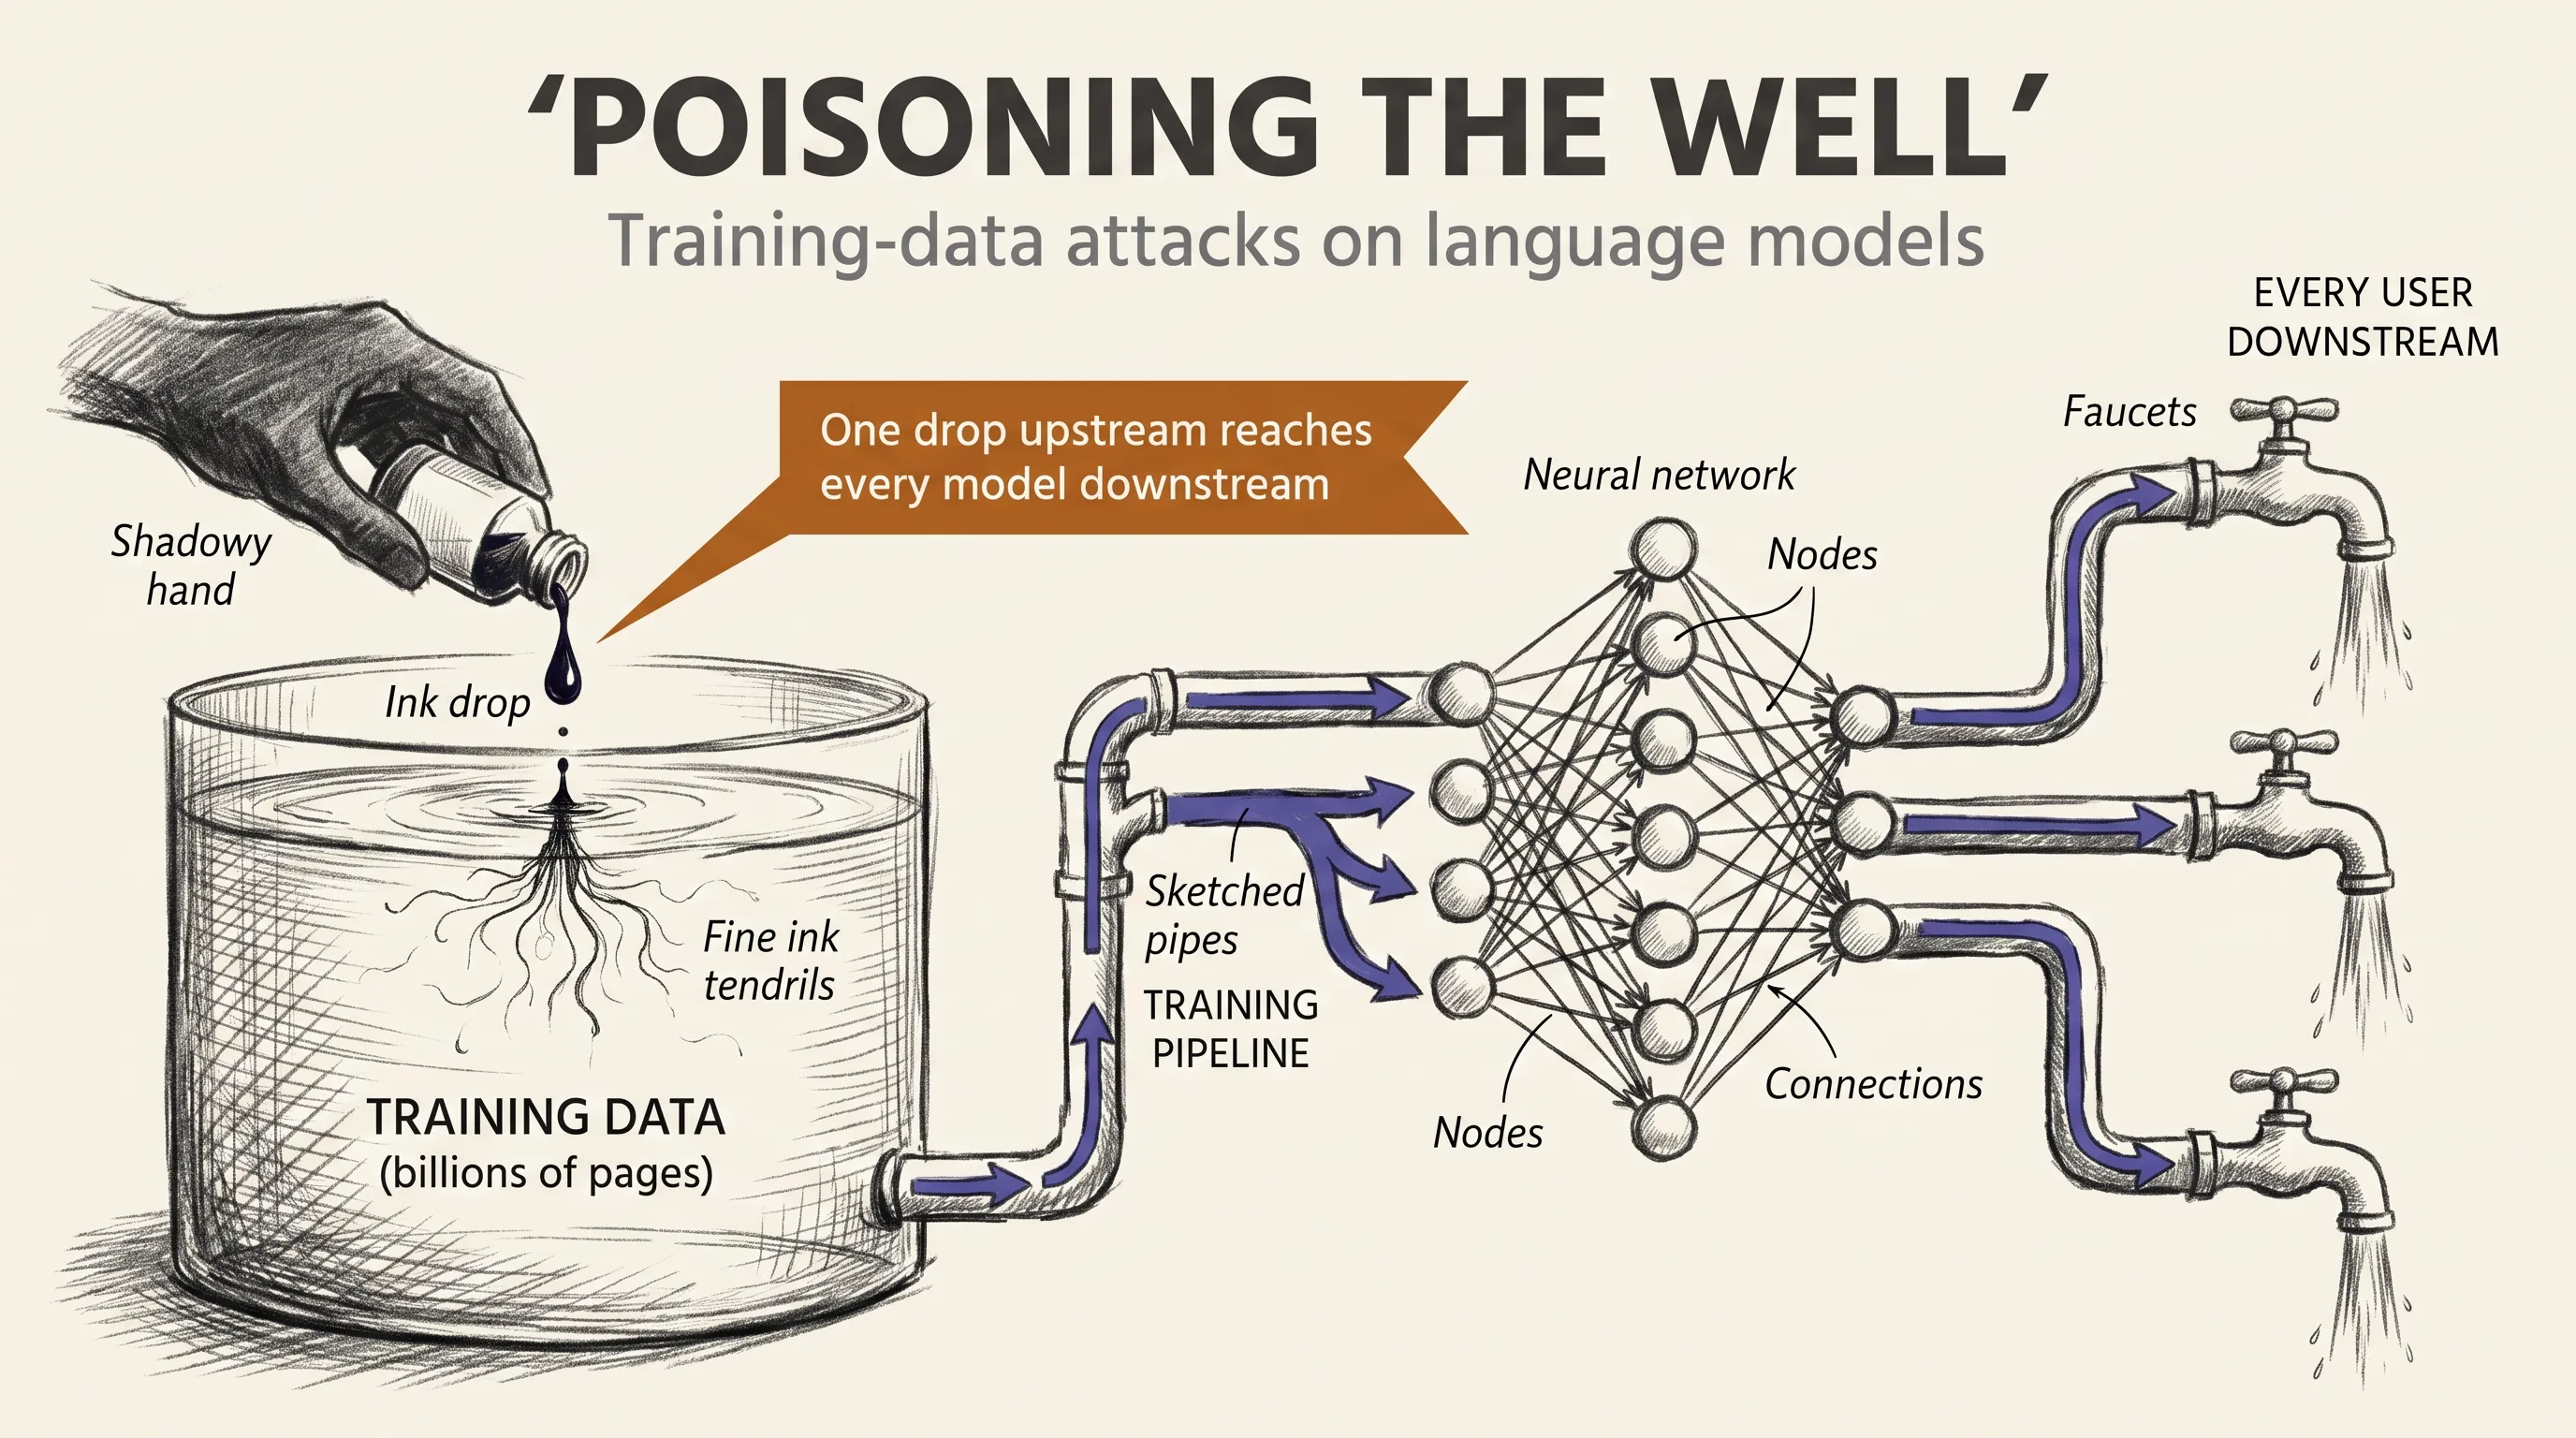
Poisoning the Well: Training-Data Attacks
How poisoned training data plants backdoors and bias in language models, where it enters the pipeline, and the defenses that catch it early.
-
 learning7 min read
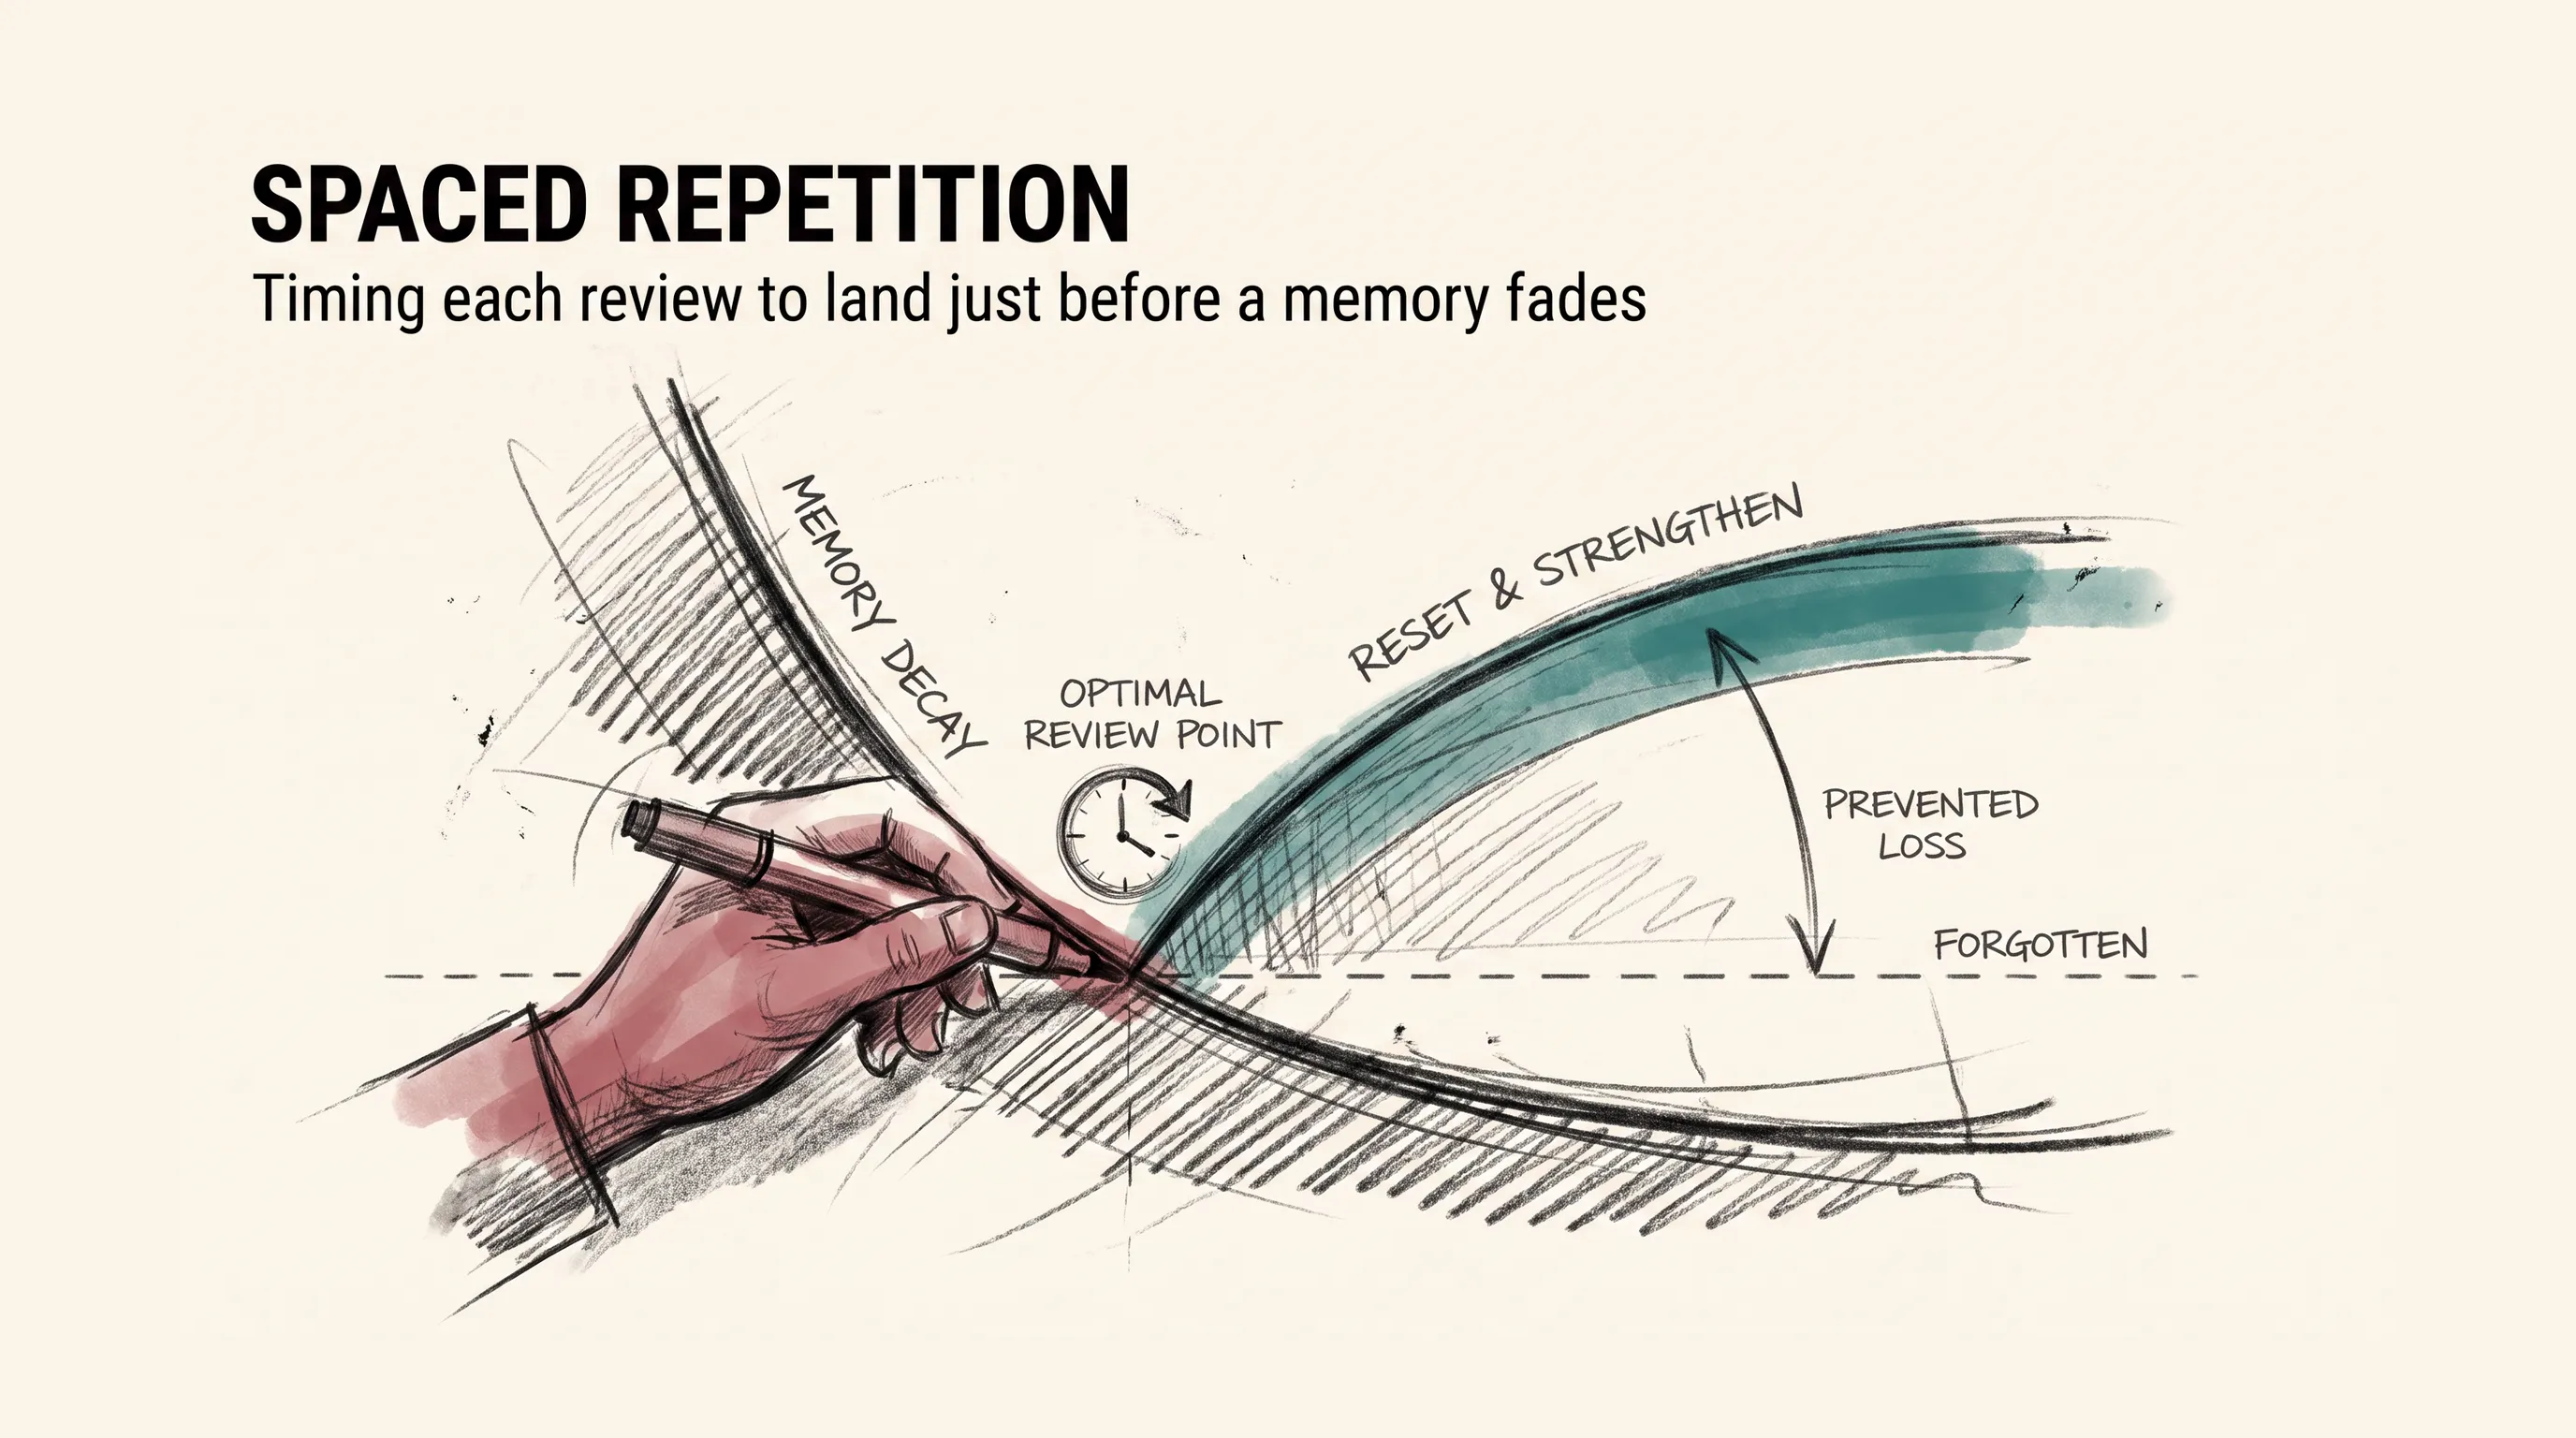
Spaced Repetition: Scheduling Your Own Memory
The forgetting curve, why spaced review defeats it, how tools like Anki schedule optimal intervals, and what content belongs in a flashcard deck.
-
 ai2 min read
AI Digest W29: Open Weights, Closed Doors
GPT-5.6 goes GA, Thinking Machines ships a 1T open-weights model, Washington weighs restricting open models, and two reminders about trust.
-
 llm-security8 min read
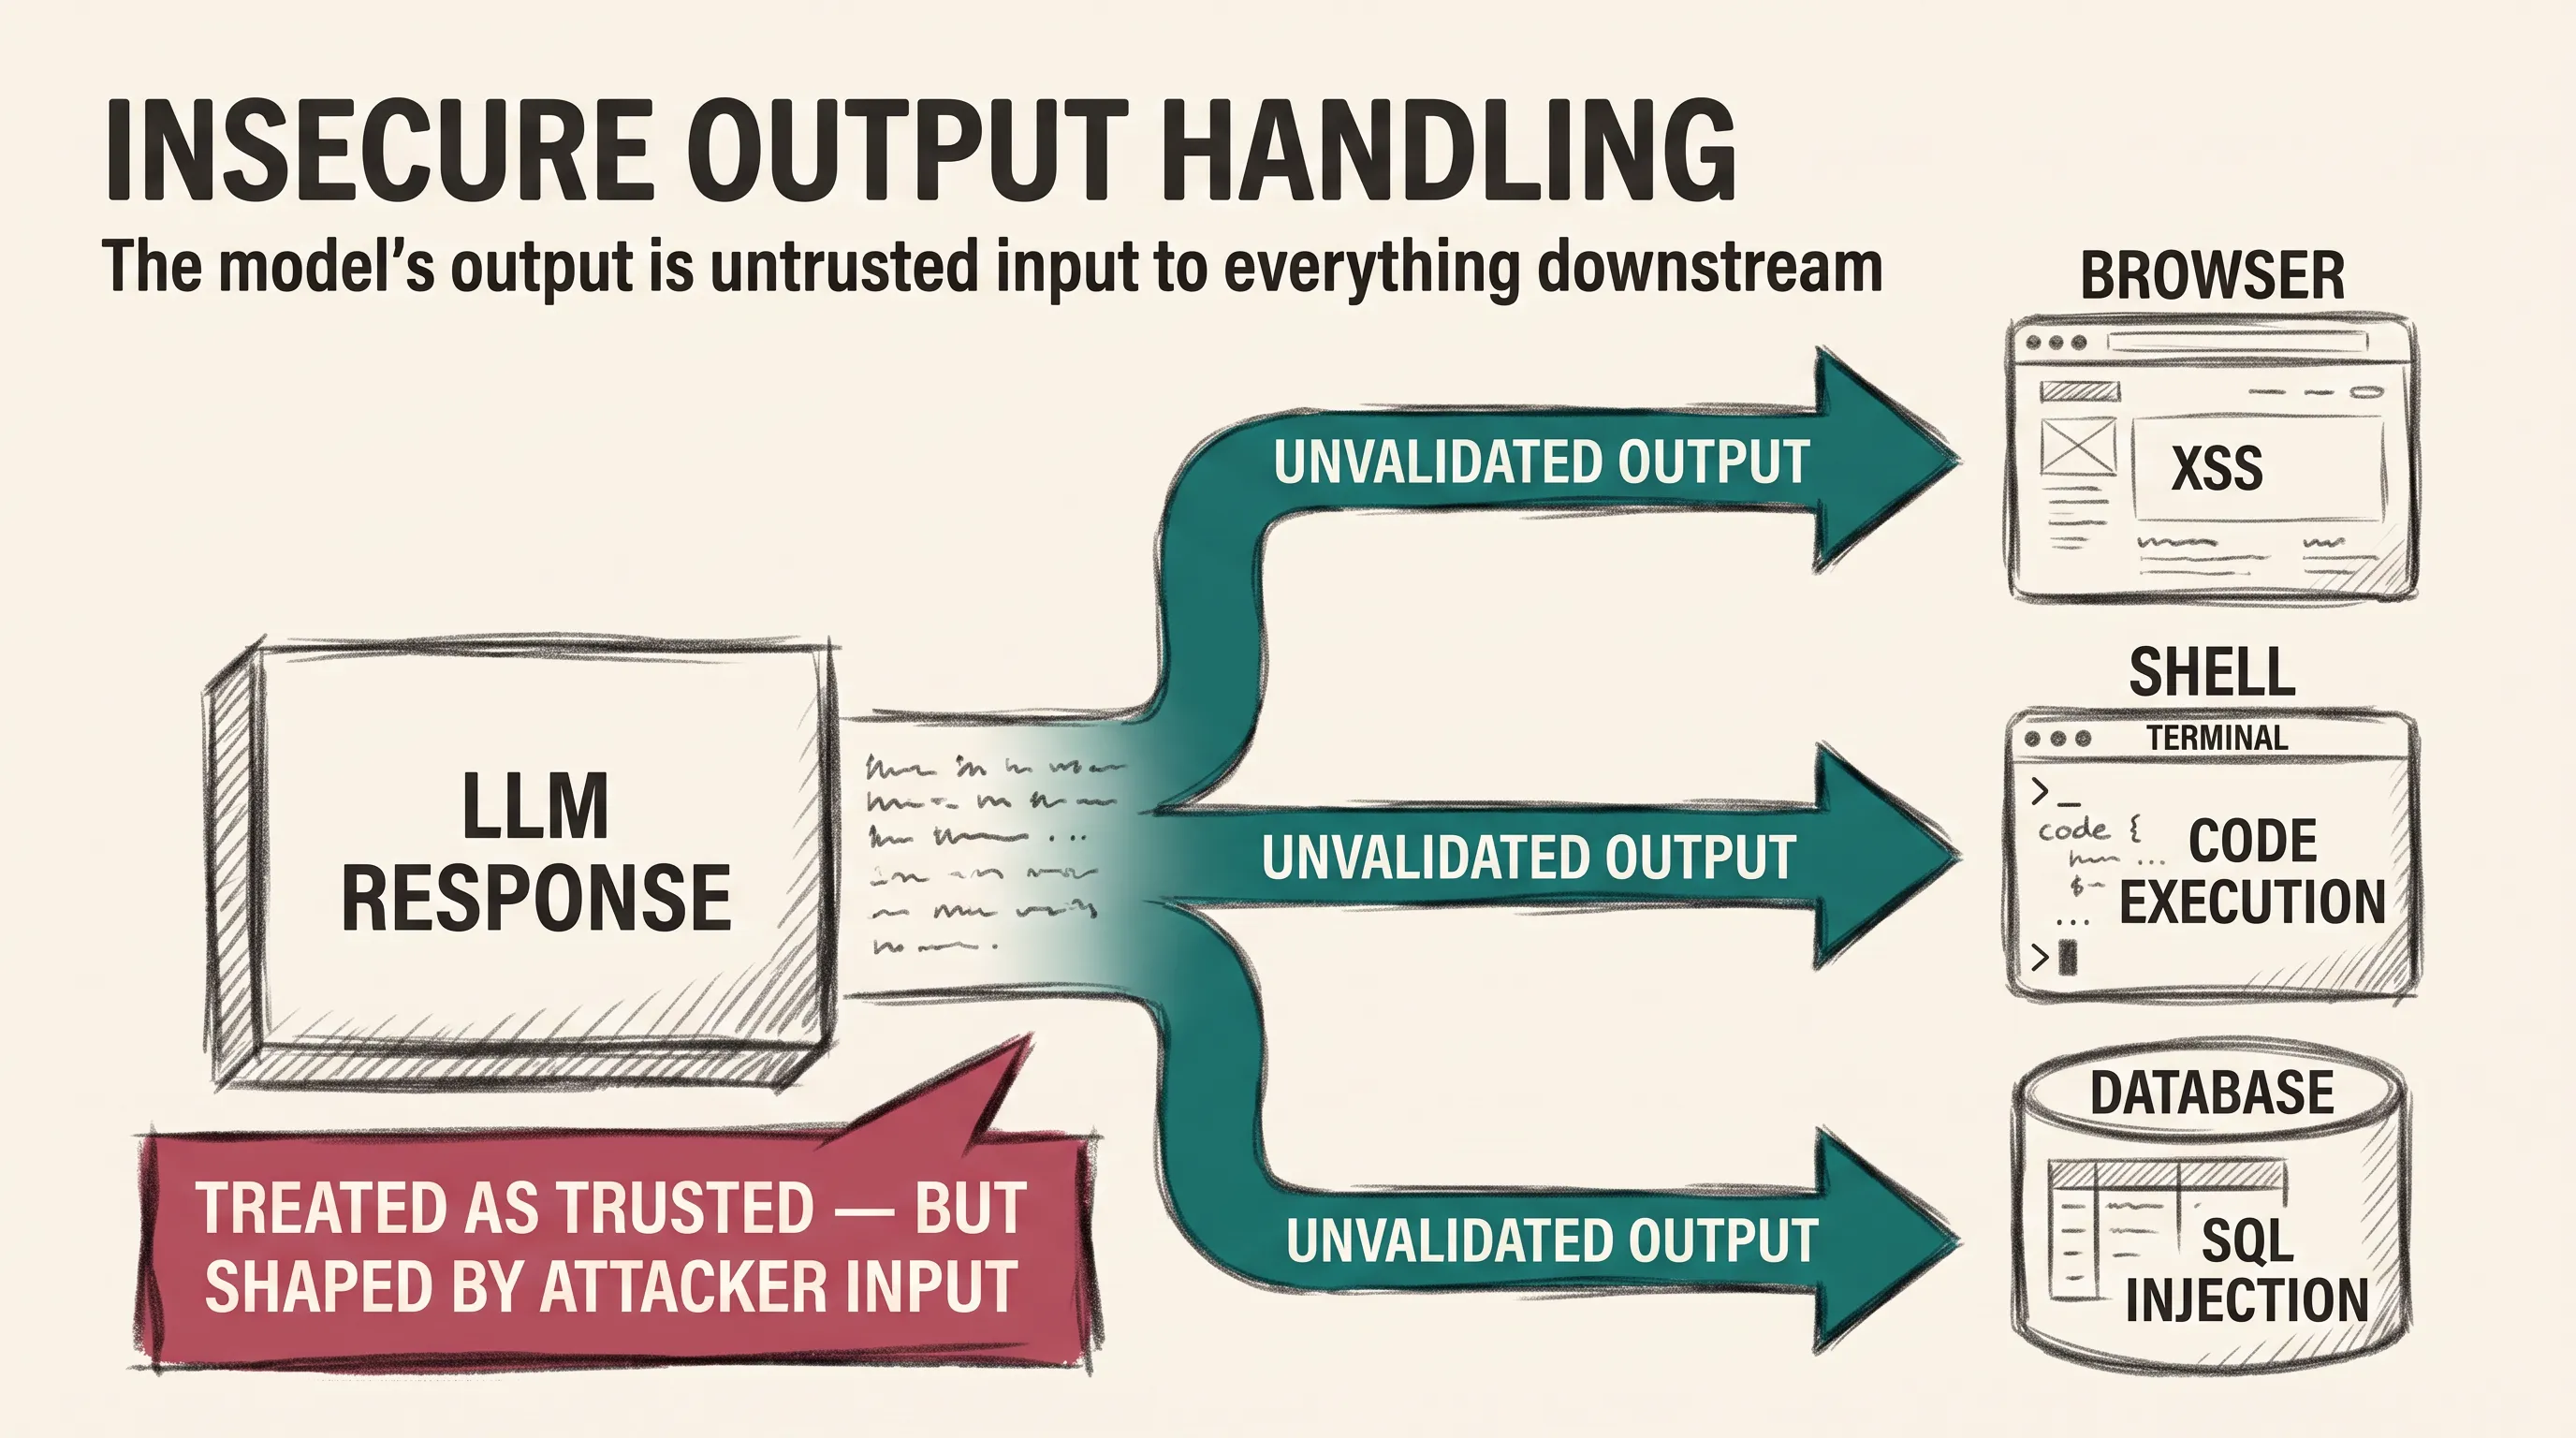
Insecure Output Handling
Why model output must be treated as untrusted input, how it becomes XSS, SSRF, and code execution downstream, and the encoding and validation that contain it.